


{
  "split": "train",
  "dataset_samples": 224,
  "checked_samples": 4,
  "samples": [
    {
      "sequence_name": "e050c15a8d_frame_007080",
      "views": 8,
      "resolution": 224,
      "valid_depth_fraction": 0.9779127240180969,
      "max_reprojection_error_px": 0.00011279189493507147,
      "max_ray_reprojection_error_px": 0.00010904046939685941,
      "centroid_distance": 1.0
    },
    {
      "sequence_name": "5f99900f09_frame_002820",
      "views": 8,
      "resolution": 224,
      "valid_depth_fraction": 0.9903116226196289,
      "max_reprojection_error_px": 0.00012302029062993824,
      "max_ray_reprojection_error_px": 0.00011108566104667261,
      "centroid_distance": 1.0
    },
    {
      "sequence_name": "47b37eb6f9_frame_002720",
      "views": 8,
      "resolution": 224,
      "valid_depth_fraction": 0.9609947800636292,
      "max_reprojection_error_px": 9.777836385183036e-05,
      "max_ray_reprojection_error_px": 8.897326188161969e-05,
      "centroid_distance": 1.0
    },
    {
      "sequence_name": "4c5c60fa76_frame_006690",
      "views": 8,
      "resolution": 224,
      "valid_depth_fraction": 0.7516716122627258,
      "max_reprojection_error_px": 0.00011736395390471444,
      "max_ray_reprojection_error_px": 0.000106735089502763,
      "centroid_distance": 1.0
    }
  ],
  "batch_shapes": {
    "rgb": [
      2,
      8,
      3,
      224,
      224
    ],
    "depth": [
      2,
      8,
      1,
      224,
      224
    ],
    "depth_valid": [
      2,
      8,
      1,
      224,
      224
    ],
    "K": [
      2,
      8,
      3,
      3
    ],
    "frame_numbers": [
      2,
      8
    ],
    "T_world_from_camera": [
      2,
      8,
      4,
      4
    ],
    "original_world_from_reference": [
      2,
      4,
      4
    ],
    "scene_scale": [
      2
    ],
    "points_world": [
      2,
      8,
      3,
      224,
      224
    ],
    "ray_origins": [
      2,
      8,
      3,
      224,
      224
    ],
    "ray_directions": [
      2,
      8,
      3,
      224,
      224
    ],
    "plucker": [
      2,
      8,
      6,
      224,
      224
    ]
  }
}
Final overfit PSNR (2000 steps, one fixed batch): 30.99 dB (SSIM 0.8710).

val_epoch000.png — columns: source views, ground truth, prediction
Training settings: Default configs/lvsm.json, except 600 epochs instead of 100. With 100 epochs, val PSNR was only 16.14 dB and still rising. Batch 4, 8 views per sample, 224 px, S = 2 source views (6 targets). Patch 8, width 384, 8 layers. AdamW, lr 2e-4, weight decay 0.05, 200 warm-up steps, cosine decay, bf16. One GPU. best.pt is from epoch 595.

Training curves
Validation metrics (best.pt, 28 val scenes):
| Source views | Target rays | PSNR ↑ | SSIM ↑ |
|---|---|---|---|
| 1 | correct | 16.06 | 0.5961 |
| 1 | shuffled | 11.59 | 0.4779 |
| 1 | none | 12.32 | 0.5193 |
| 2 | correct | 17.48 | 0.6107 |
| 2 | shuffled | 11.16 | 0.4555 |
| 2 | none | 12.29 | 0.5169 |
| 4 | correct | 18.69 | 0.6351 |
| 4 | shuffled | 11.20 | 0.4522 |
| 4 | none | 12.35 | 0.5285 |
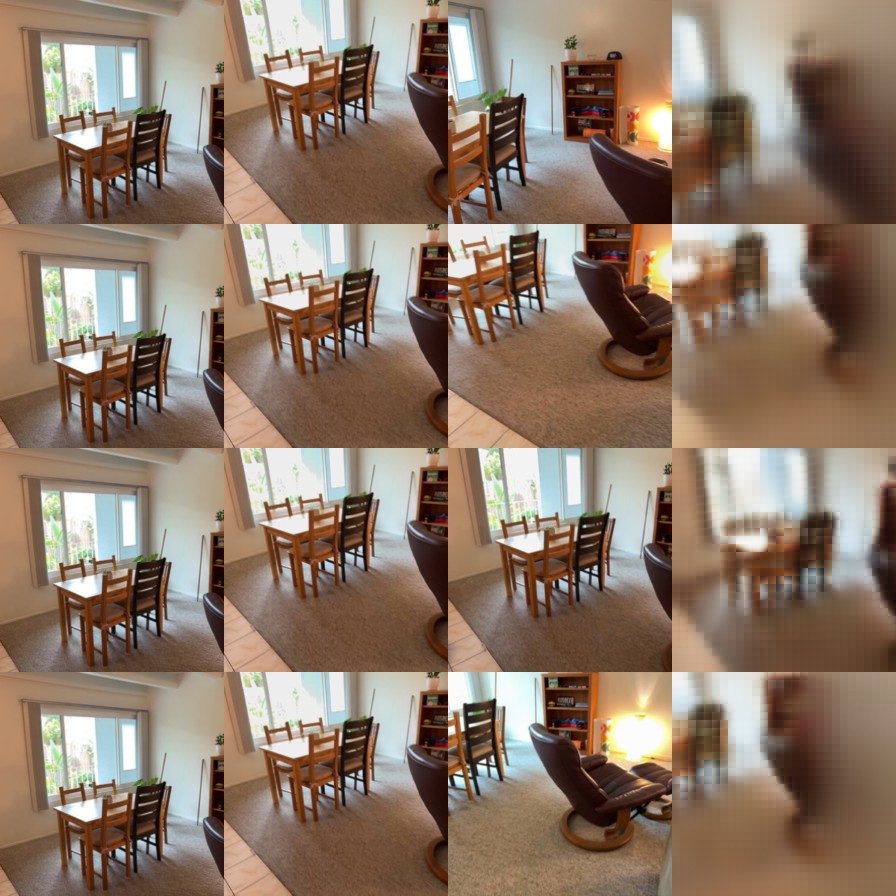
Training visualization (val_epoch595.png) — columns: source views, ground truth, prediction
Evaluation visualizations (columns: source views, ground truth, prediction):
|
|
|
|
|
|
Discussion:
Question: if we train with a random number of source views, does the model handle 1, 2 and 4 views better?
Setting: same as Q2.2 (same config, 600 epochs, same seed). The only change: each training step picks S at random from {1, 2, 3, 4} (option train_source_views, configs/lvsm_randS.json). Validation and best.pt selection still use S = 2.
| Eval S | Target rays | PSNR fixed S=2 | PSNR random S | Δ PSNR | SSIM fixed S=2 | SSIM random S |
|---|---|---|---|---|---|---|
| 1 | correct | 16.06 | 16.10 | +0.03 | 0.5961 | 0.5978 |
| 1 | shuffled | 11.59 | 11.62 | +0.03 | 0.4779 | 0.4810 |
| 1 | none | 12.32 | 12.54 | +0.22 | 0.5193 | 0.5298 |
| 2 | correct | 17.48 | 17.60 | +0.12 | 0.6107 | 0.6137 |
| 2 | shuffled | 11.16 | 11.15 | -0.01 | 0.4555 | 0.4536 |
| 2 | none | 12.29 | 12.51 | +0.22 | 0.5169 | 0.5258 |
| 4 | correct | 18.69 | 18.96 | +0.26 | 0.6351 | 0.6408 |
| 4 | shuffled | 11.20 | 11.13 | -0.06 | 0.4522 | 0.4435 |
| 4 | none | 12.35 | 12.53 | +0.18 | 0.5285 | 0.5339 |

Training curves (validation uses S=2)
|
|
|
|
Conclusions:

Overfit loss curve (total, camera, depth)
| Ground truth | Prediction (predicted camera + depth) |
|---|---|
|
|
Training settings: Default configs/vggt.json: 1000 epochs, 8 views per sample, 224 px, batch 16 on 2 GPUs (DDP). Frozen DINOv2 ViT-B/14, 8 frame/global blocks (width 384). AdamW, lr 6e-4, weight decay 0.01, 10 warm-up epochs, cosine decay. Loss weights: camera 5, depth 1. bf16. best.pt (lowest val loss) is from epoch 952.

Normal-training loss curve (total, camera, depth; train and validation)
Metrics (best.pt, 28 scenes per split, 8 views):
| Split | AbsRel ↓ | δ1 ↑ | Rot AUC@5 | Rot AUC@15 | Rot AUC@30 | Trans AUC@5 | Trans AUC@15 | Trans AUC@30 | Pose AUC@5 | Pose AUC@15 | Pose AUC@30 |
|---|---|---|---|---|---|---|---|---|---|---|---|
| val | 0.1375 | 0.8431 | 0.1689 | 0.4949 | 0.6930 | 0.0138 | 0.0830 | 0.2027 | 0.0048 | 0.0666 | 0.1806 |
| test | 0.1551 | 0.7918 | 0.2084 | 0.5151 | 0.7097 | 0.0102 | 0.0639 | 0.1910 | 0.0010 | 0.0346 | 0.1628 |
GT vs. prediction, four val scenes:
| Ground truth | Prediction |
|---|---|
|
|
|
|
|
|
|
|
Discussion:
Question: the model is trained with 8 views. What happens to accuracy, runtime and memory with 2, 4, 8, 16 or 24 views at test time?
Setting: same Q3.2 checkpoint, no retraining (scripts/vggt_num_views.py). Views come from the first 32 frames, seed 825. Runtime: average of 10 forward passes on 4 samples, divided by 4. Memory: peak GPU memory during the forward pass (without weights).
val
| Views | AbsRel ↓ | δ1 ↑ | Rot AUC@30 | Trans AUC@30 | Pose AUC@5 | Pose AUC@30 | Forward ms / sample | Peak inference memory (MB) |
|---|---|---|---|---|---|---|---|---|
| 2 | 0.1205 | 0.8545 | 0.7000 | 0.2667 | 0.0143 | 0.2250 | 5.2 | 400 |
| 4 | 0.1235 | 0.8584 | 0.6702 | 0.2111 | 0.0036 | 0.1855 | 4.4 | 450 |
| 8 | 0.1375 | 0.8430 | 0.6935 | 0.2035 | 0.0051 | 0.1814 | 8.1 | 769 |
| 16 | 0.1666 | 0.8100 | 0.6593 | 0.1670 | 0.0018 | 0.1412 | 17.2 | 1411 |
| 24 | 0.1697 | 0.7960 | 0.6672 | 0.1726 | 0.0020 | 0.1483 | 25.4 | 2054 |
test
| Views | AbsRel ↓ | δ1 ↑ | Rot AUC@30 | Trans AUC@30 | Pose AUC@5 | Pose AUC@30 | Forward ms / sample | Peak inference memory (MB) |
|---|---|---|---|---|---|---|---|---|
| 2 | 0.1207 | 0.8389 | 0.7250 | 0.1905 | 0.0000 | 0.1524 | 5.6 | 400 |
| 4 | 0.1407 | 0.8153 | 0.7075 | 0.2262 | 0.0036 | 0.1835 | 4.8 | 450 |
| 8 | 0.1551 | 0.7917 | 0.7102 | 0.1908 | 0.0010 | 0.1627 | 8.0 | 769 |
| 16 | 0.1698 | 0.7799 | 0.7078 | 0.1848 | 0.0021 | 0.1589 | 17.2 | 1411 |
| 24 | 0.1687 | 0.7771 | 0.7209 | 0.1865 | 0.0018 | 0.1621 | 25.5 | 2054 |

Accuracy, runtime and memory vs. number of views
Conclusions:


