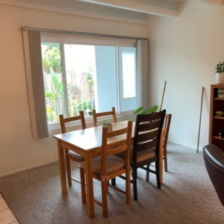
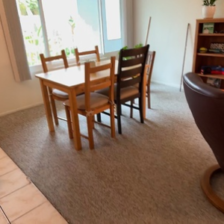
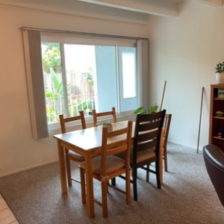
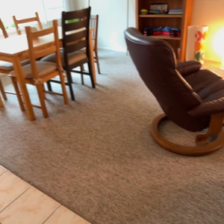
Original world frame (meters)First-camera frame (normalized)
Training scene 2
Original world frame (meters)First-camera frame (normalized)
Canonicalization transforms cameras and points into the first camera frame and divides translations, depth and points by the valid-point centroid distance. World-space ray directions are normalized inverse-intrinsics pixel directions rotated by the camera pose. The Plucker moment is the camera center cross the ray direction.
2. Novel-View Synthesis with Mini-LVSM (40 points)
2.1. Fixed-batch overfitting (10 points)
After 2000 updates on one fixed batch, overfit PSNR reaches 38.62 dB.
Target 1
Source view 1Source view 2Ground truthPrediction
Target 2
Source view 1Source view 2Ground truthPrediction
Target 3
Source view 1Source view 2Ground truthPrediction
Target 4
Source view 1Source view 2Ground truthPrediction
2.2. Training and evaluation (30 points)
Training uses 8 views, 2 source views, 224-pixel images, 16-pixel patches, width 384, 8 transformer blocks, batch size 2 and AdamW with peak learning rate 0.0002 for 100 epochs.
Full training: training and validation MSE.Full training: training and validation PSNR (dB).
Training visualization from epoch 90; the ablation images below use the best validation checkpoint.
With correct rays, increasing sources from 1 to 2 to 4 raises PSNR from 15.05 to 15.94 to 16.54 dB, although the remaining target views also change.
With two sources, correct rays score 15.94 dB, shuffled rays 11.47 dB and zero rays 12.46 dB; the model uses target-ray information, but its predictions remain blurry with visible patch boundaries.
2.3. Patch size (10 bonus points)
I compare 16-pixel and 32-pixel patches using the same training split, seed, resolution, source count, transformer width/depth and 100 epochs.
Evaluation uses identical source images, target images and rays across 28 test scenes and frame-sampling seeds 825, 826 and 827.
Condition
PSNR (dB)
SSIM
Median inference (ms)
Live memory (MB)
16-pixel patches
16.1355
0.5408
39.0
79.3
32-pixel patches
15.7973
0.5396
10.7
99.7
For both bonus experiments, runtime and memory are medians over 150 forward passes at batch size 1; memory measures live allocation after inference, not peak usage.
Validation example
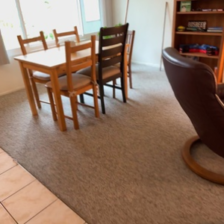
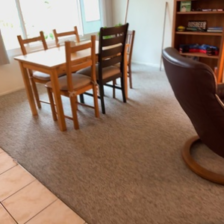
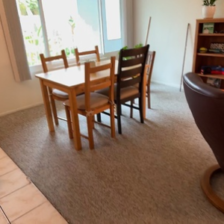
Ground truth16-pixel patches32-pixel patches
The 32-pixel model runs 3.65 times faster with slightly lower PSNR and higher live memory: larger patches reduce attention tokens but enlarge the projection layers. Both predictions lose furniture detail, and the 32-pixel result is smoother; these single-seed training runs do not establish an optimal patch size.
3. Multi-View Geometry with Mini-VGGT (40 points)
3.1. Single-clip overfitting (10 points)
Single-clip overfitting: total, camera and depth loss.
I fit one fixed eight-view training clip for 40 epochs.
Training scene 1
Ground truthPrediction
3.2. Training and held-out evaluation (30 points)
Training and held-out evaluation: total, camera and depth loss.
Training uses frozen DINOv2 ViT-B/14, width 384, 8 frame/global block pairs, 8 views, sampling range 32, 224-pixel images, batch size 2, AdamW learning rate 0.0006 and 100 epochs; the best validation checkpoint is epoch 96.
Validation scene 1
Ground truthPrediction
Validation scene 2
Ground truthPrediction
Validation scene 3
Ground truthPrediction
Validation scene 4
Ground truthPrediction
Metric
Validation
Test
Depth AbsRel
0.1784
0.1934
Depth delta1
0.7612
0.7352
Rotation AUC at 5 deg
0.1199
0.1311
Rotation AUC at 15 deg
0.2773
0.3086
Rotation AUC at 30 deg
0.4410
0.4979
Translation AUC at 5 deg
0.0041
0.0056
Translation AUC at 15 deg
0.0394
0.0303
Translation AUC at 30 deg
0.1004
0.0888
Joint pose AUC at 5 deg
0.0026
0.0041
Joint pose AUC at 15 deg
0.0287
0.0215
Joint pose AUC at 30 deg
0.0841
0.0746
Evaluation uses both full splits, with 8 views from the first 32 prepared frames, 224-pixel images and seed 825.
Scene 1 merges separated surfaces, scene 2 makes surfaces fuzzy and clusters cameras, scene 3 obscures the hallway opening and introduces tall structures near its entrance that are absent from the ground truth, and scene 4 clusters camera positions and duplicates surfaces; the model recovers coarse extent but struggles to fuse held-out views.
3.3. Number of input views (10 bonus points)
I compare 2, 4 and 8 input views using one fixed checkpoint across 28 test scenes and frame-sampling seeds 825, 826 and 827, scoring the same first two views and camera pair with unchanged eight-view normalization.
Condition
Depth AbsRel
Depth delta1
Joint pose AUC at 30 deg
Median inference (ms)
Live memory (MB)
2 input views
0.1942
0.7384
0.0599
47.6
585.3
4 input views
0.1896
0.7392
0.0615
84.2
587.3
8 input views
0.1932
0.7322
0.0690
165.7
592.0
Additional views provide no consistent improvement across the depth and pose metrics, while runtime and live memory increase because more views require more encoder and attention work; conclusions are limited to this checkpoint, which was trained with eight views.