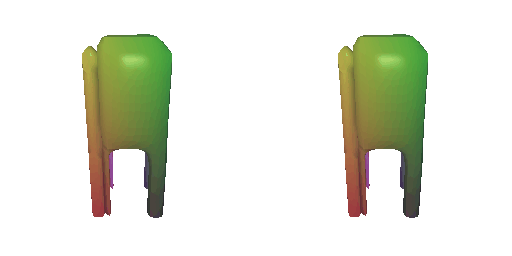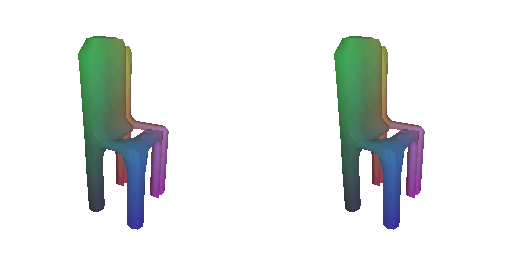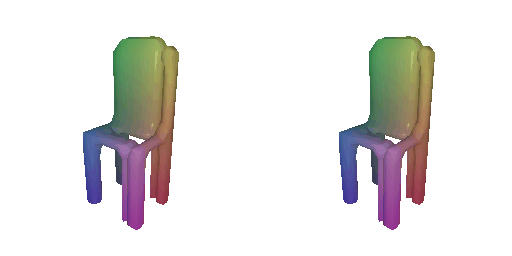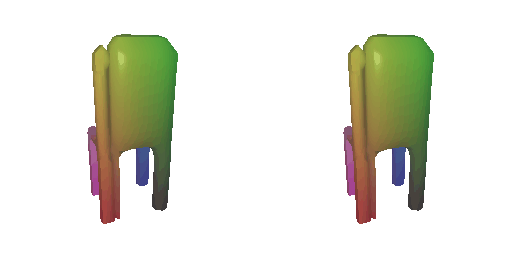
Left: optimized voxel grid. Right: ground truth.
Left: optimized point cloud. Right: ground truth.
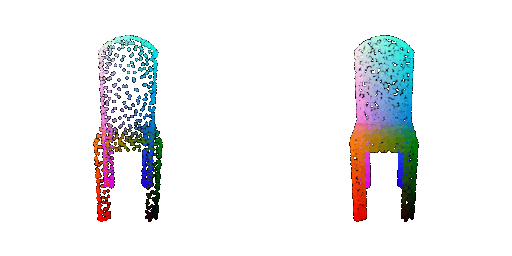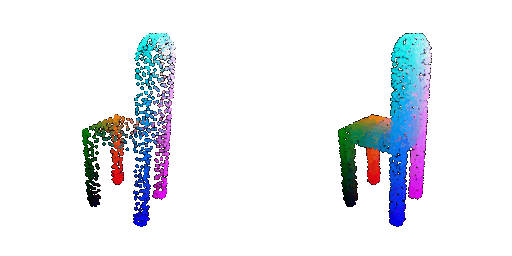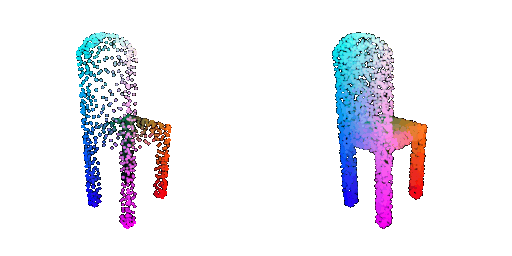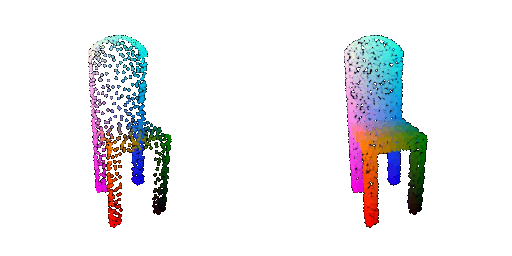
Left: prediction. Right: ground truth.
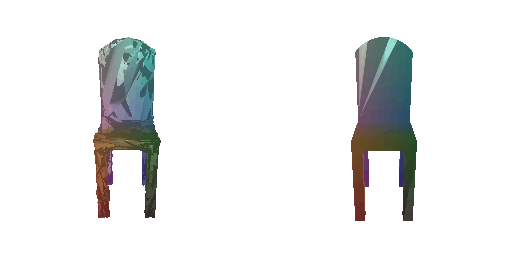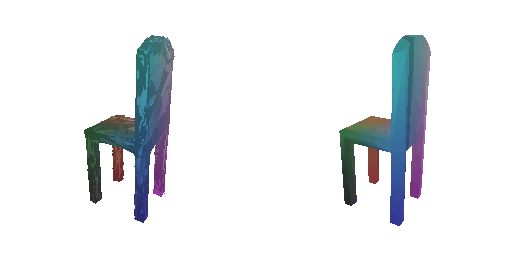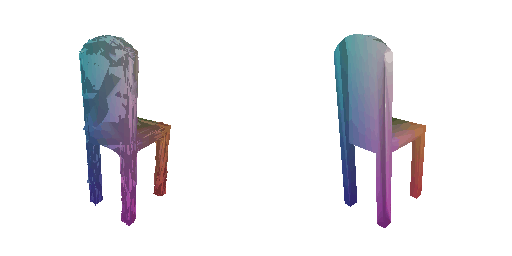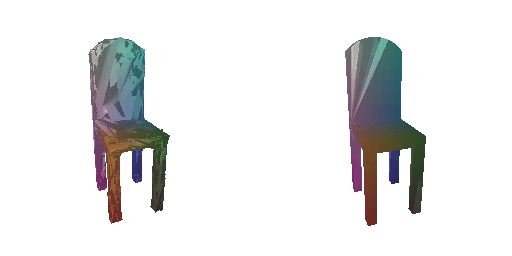
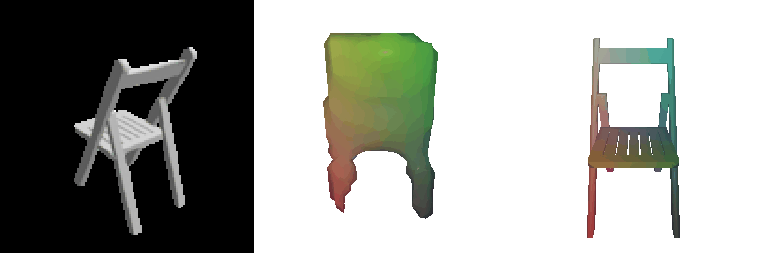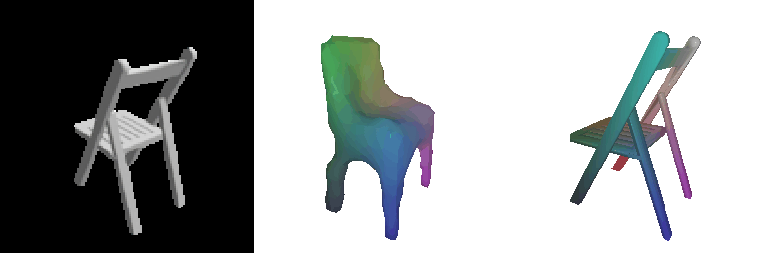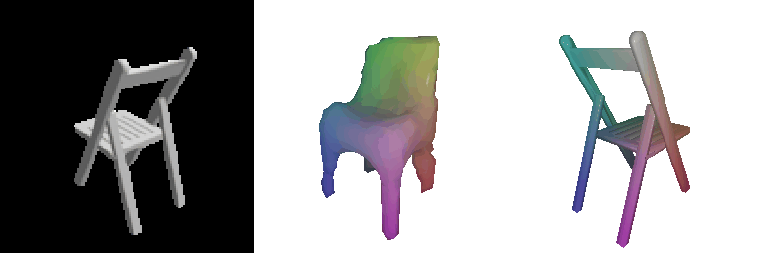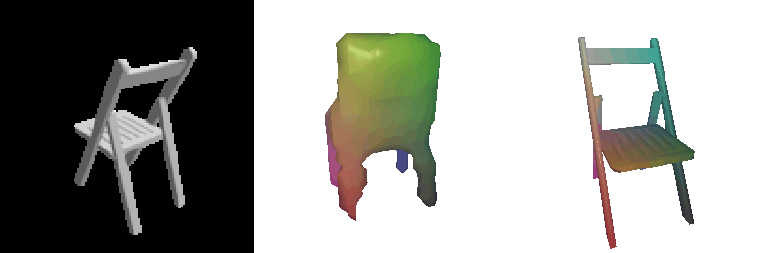
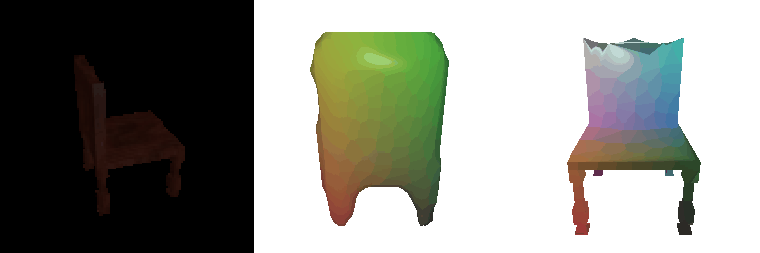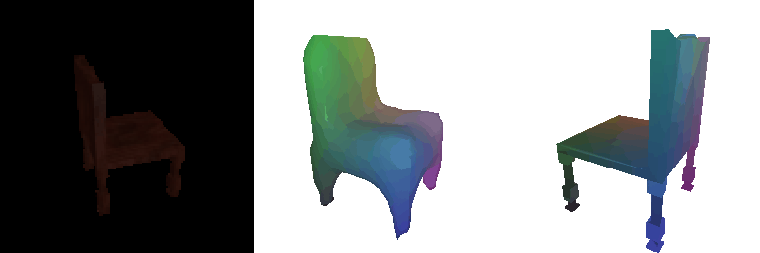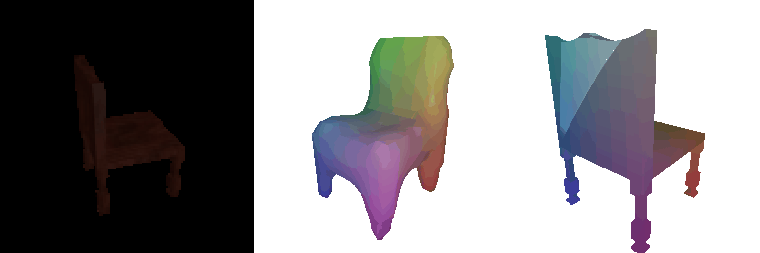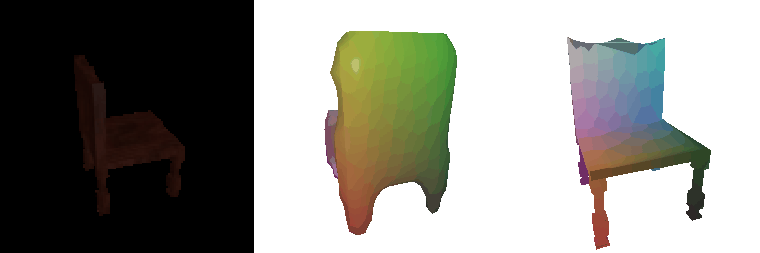
input RGB | prediction | ground-truth mesh
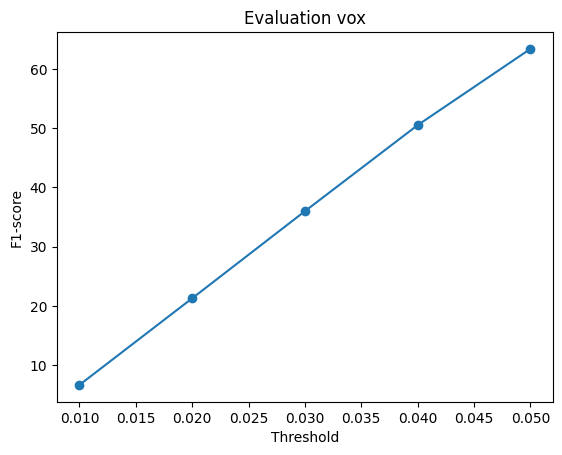
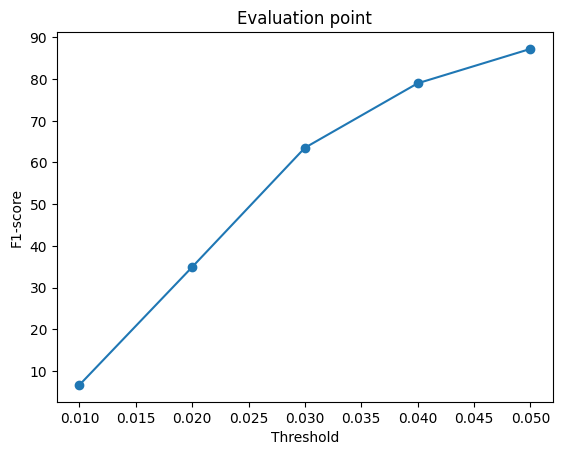
F1@0.05 = 63.40
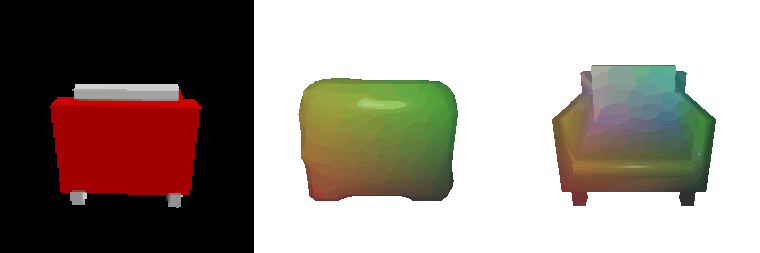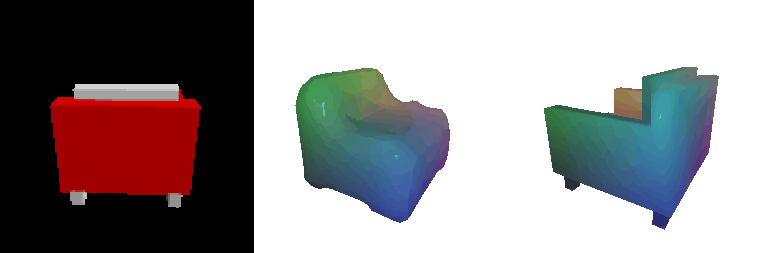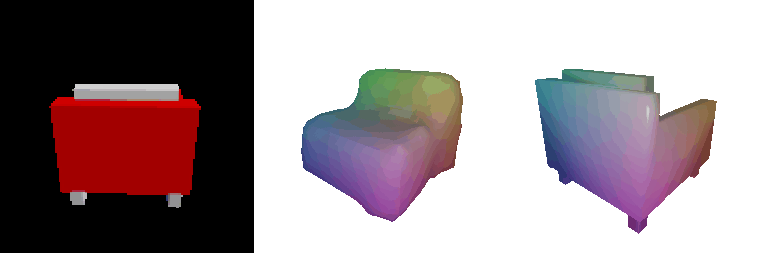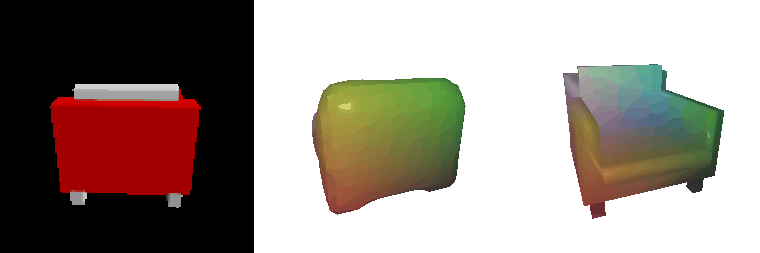
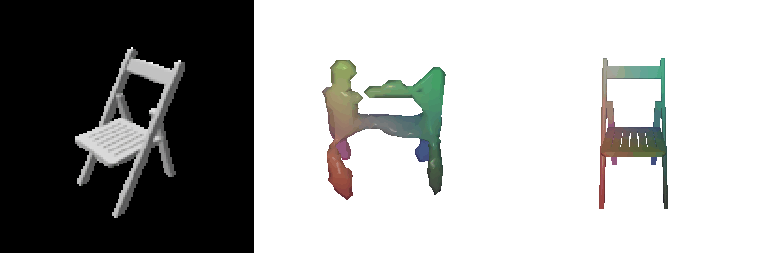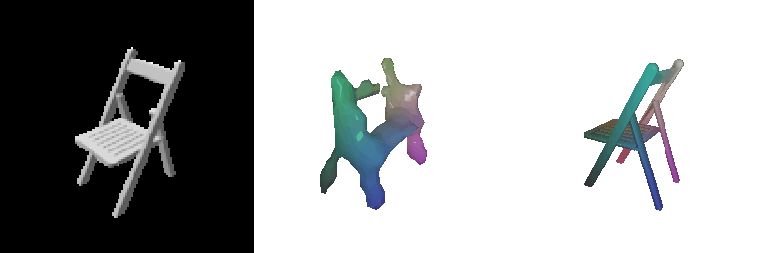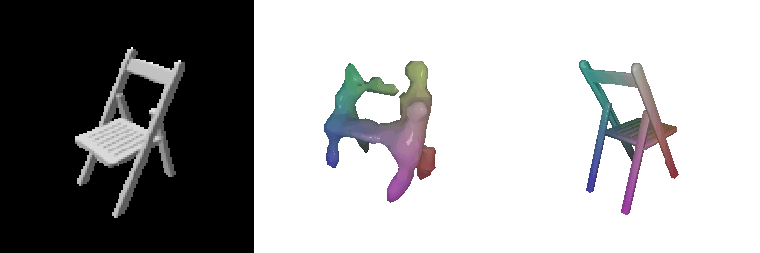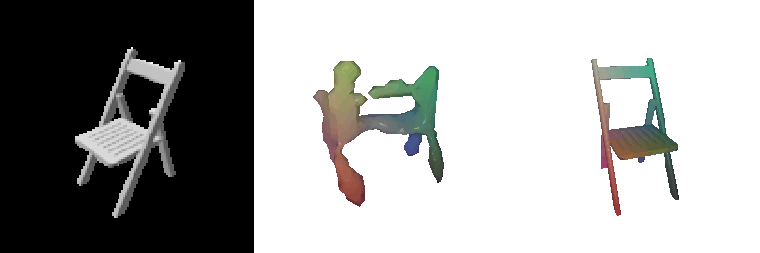
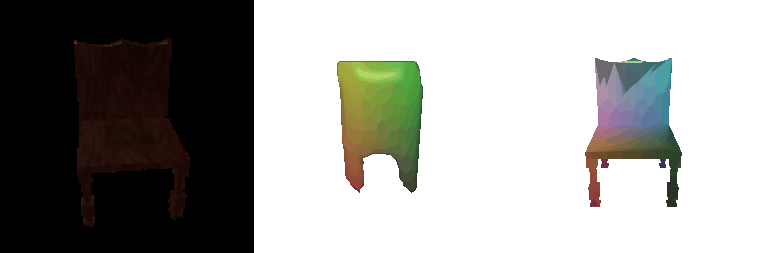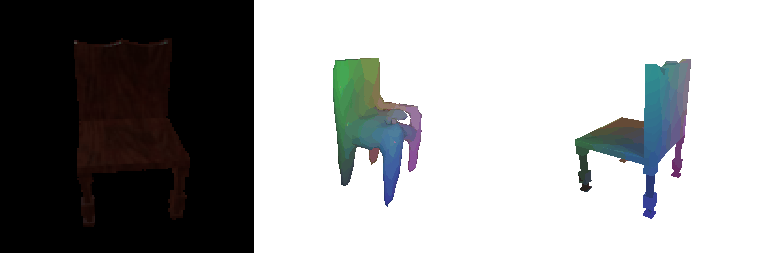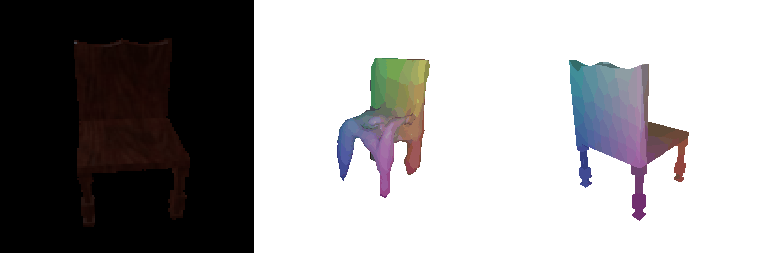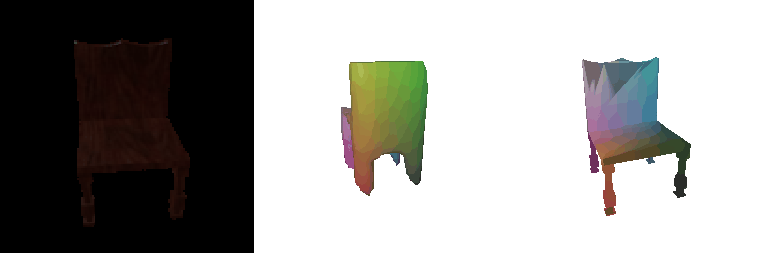
F1@0.05 = 87.24
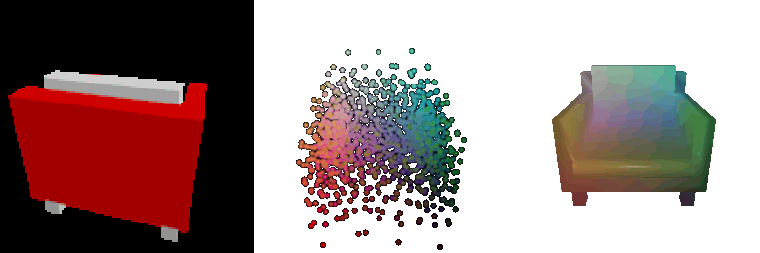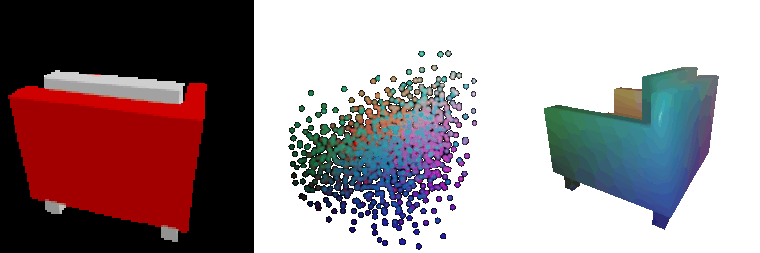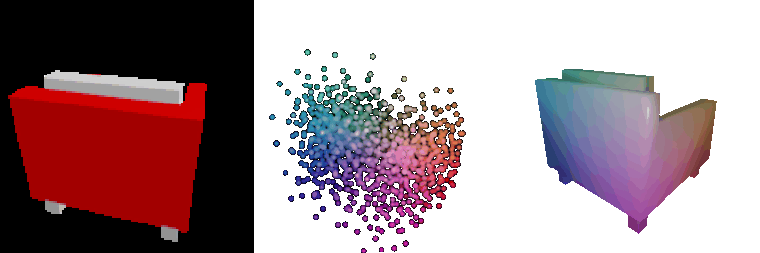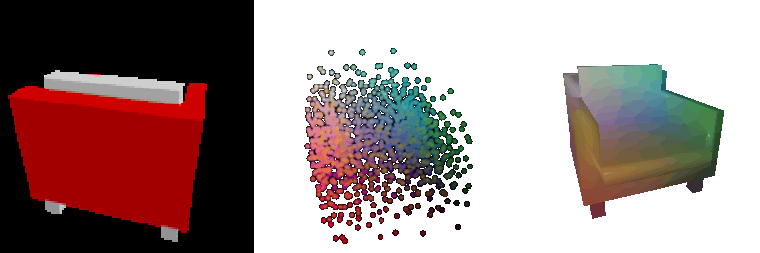
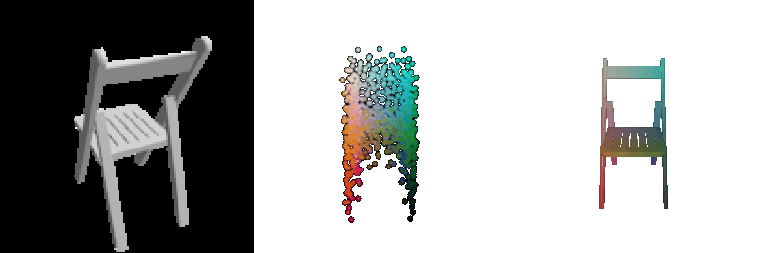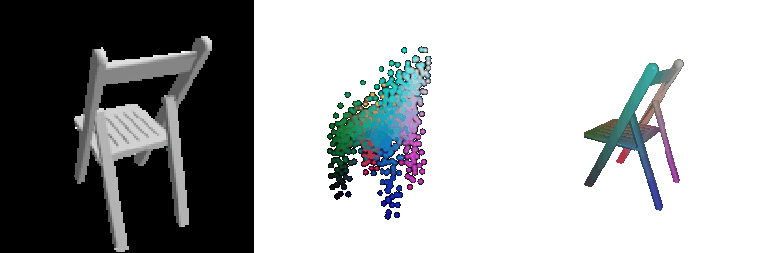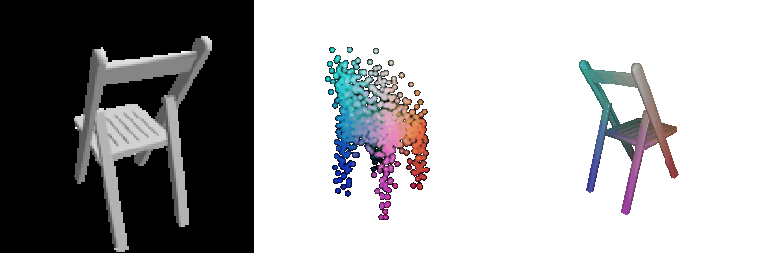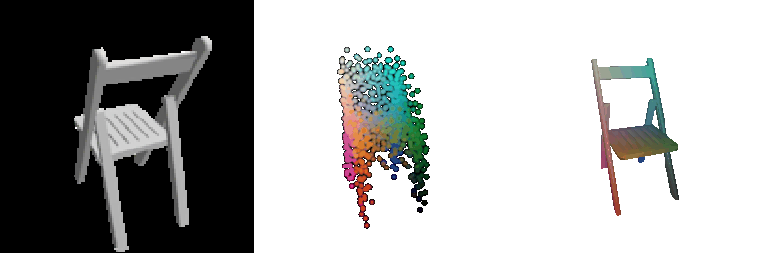
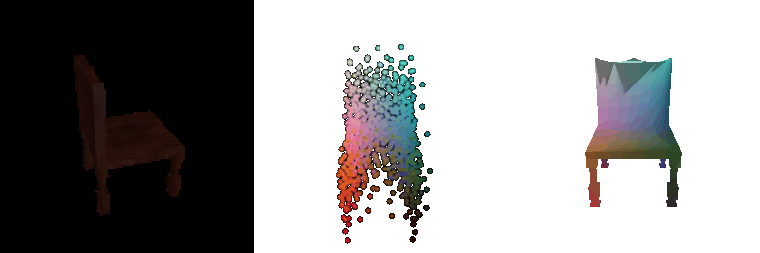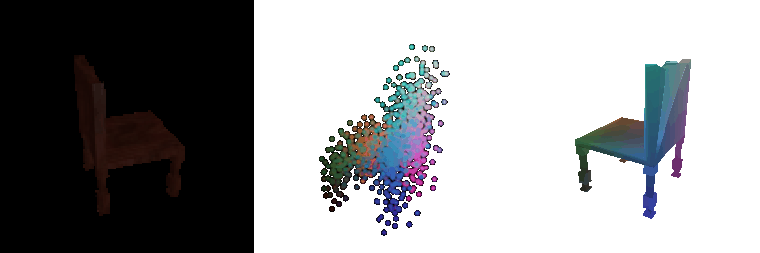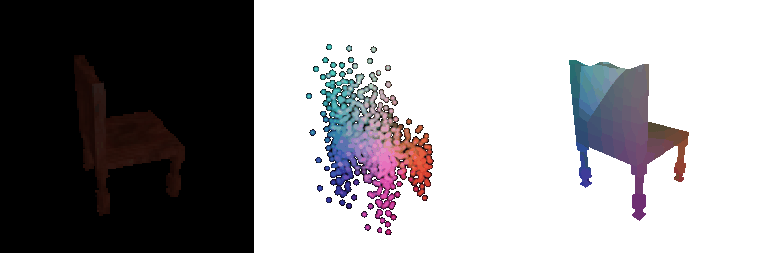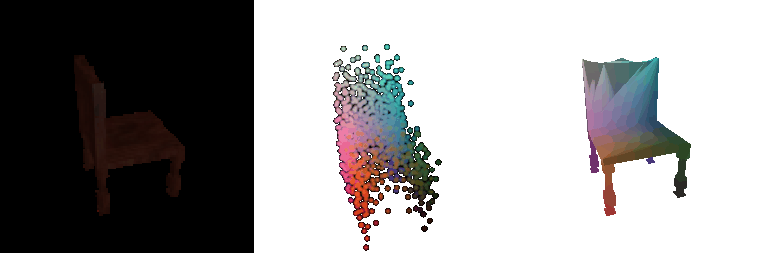
F1@0.05 = 82.74
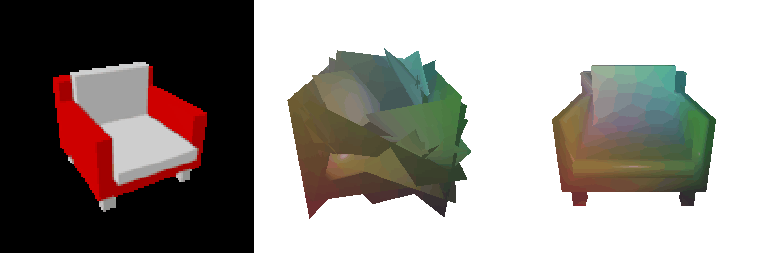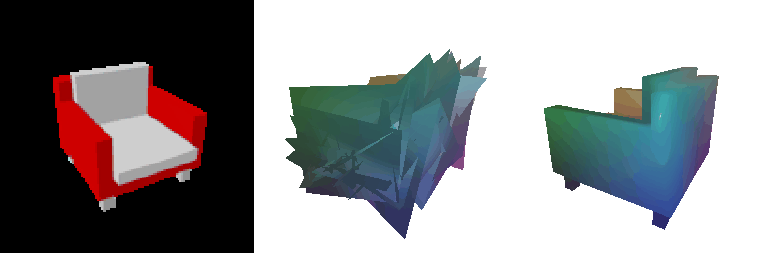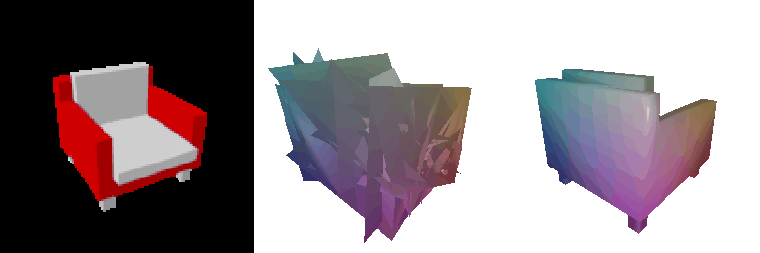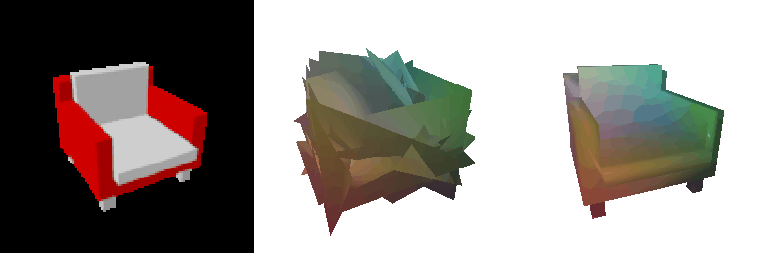
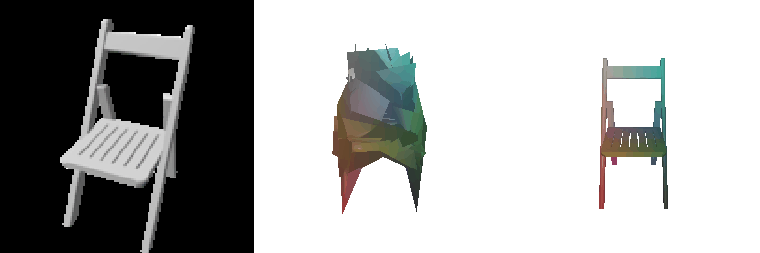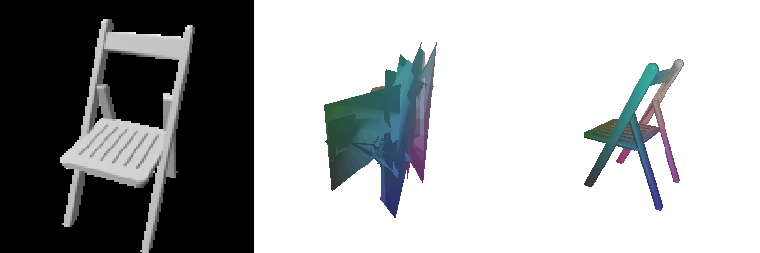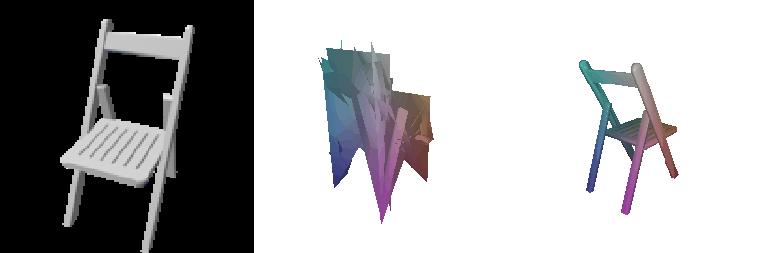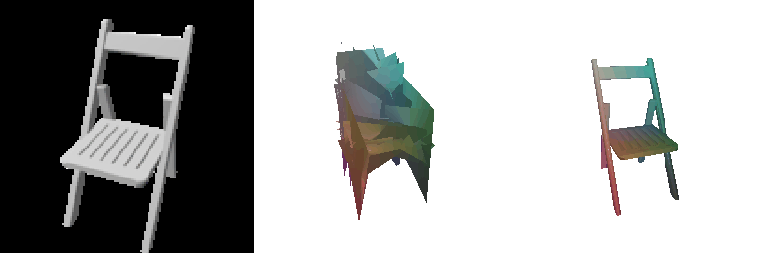
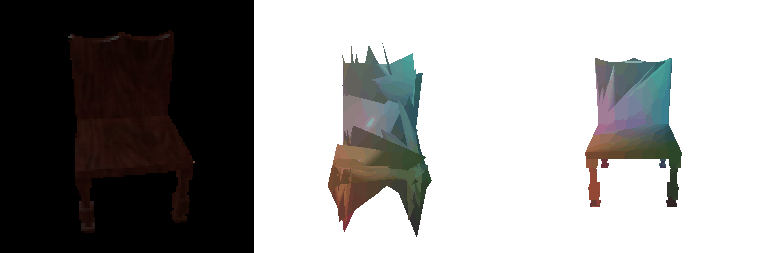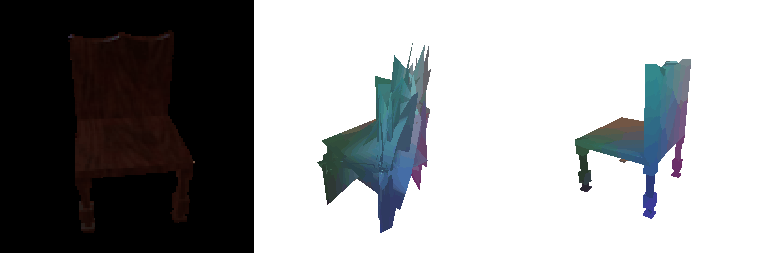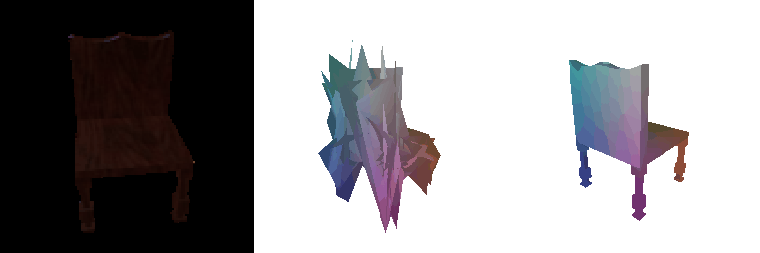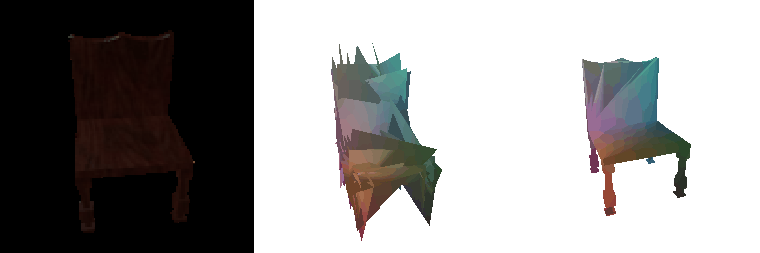
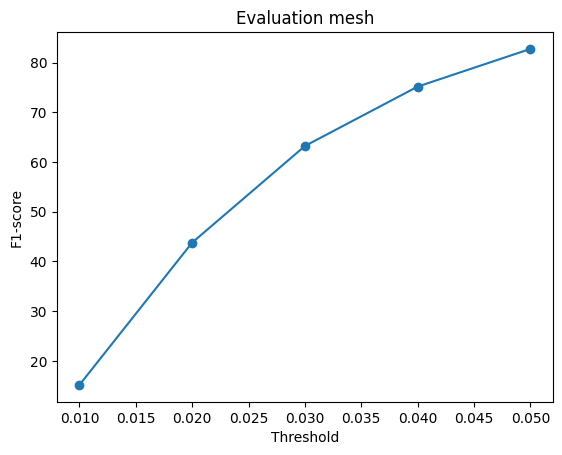
| Representation | F1@0.05 |
|---|---|
| Point cloud | 87.24 |
| Mesh | 82.74 |
| Voxel | 63.40 |
The point cloud representation wins, as it has less constraints compared to mesh & voxels. Mesh representation is restricted by topology, whereas voxels are restricted by resolution.
| init | F1@0.05 |
|---|---|
ico_sphere(4) (radius 1.0), free offsets |
82.74 |
| sphere scaled to 0.4, offsets capped at ±0.5 | 58.76 |
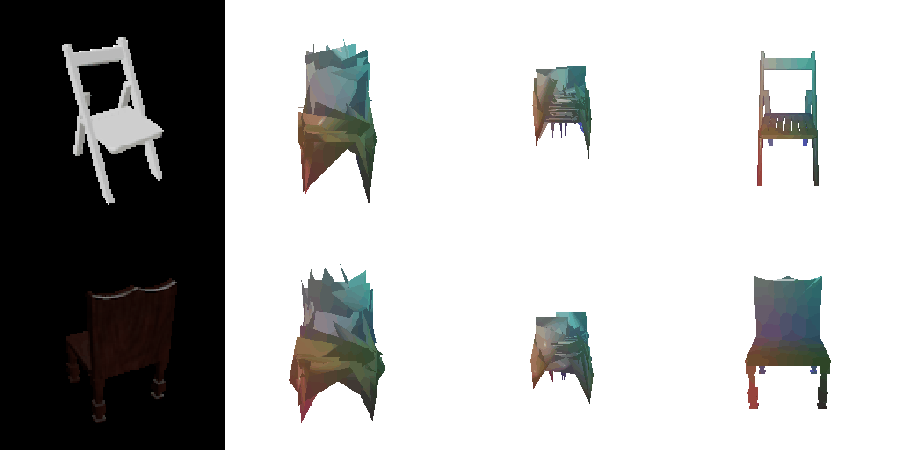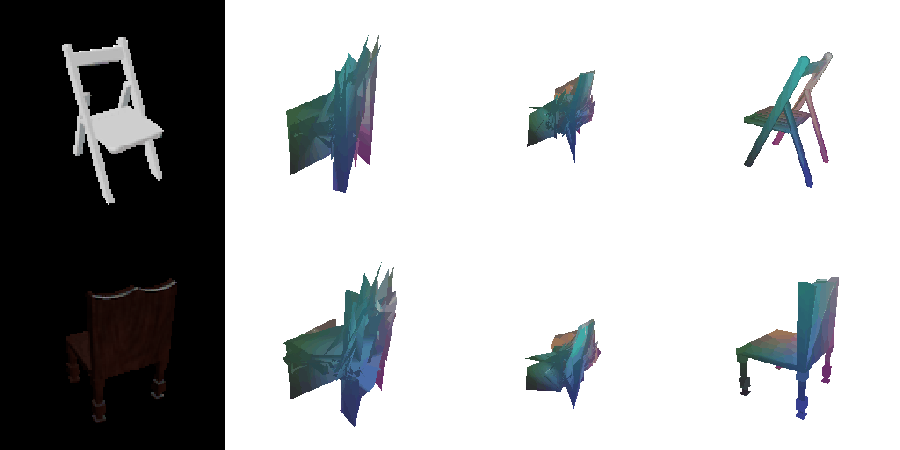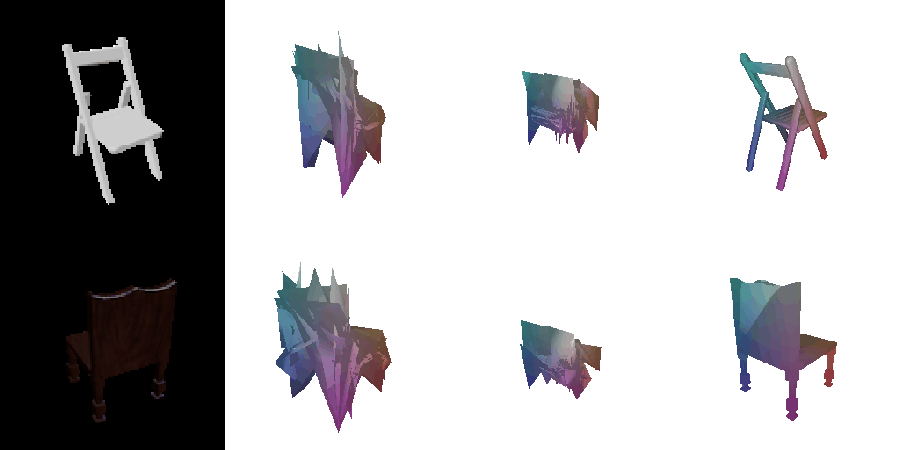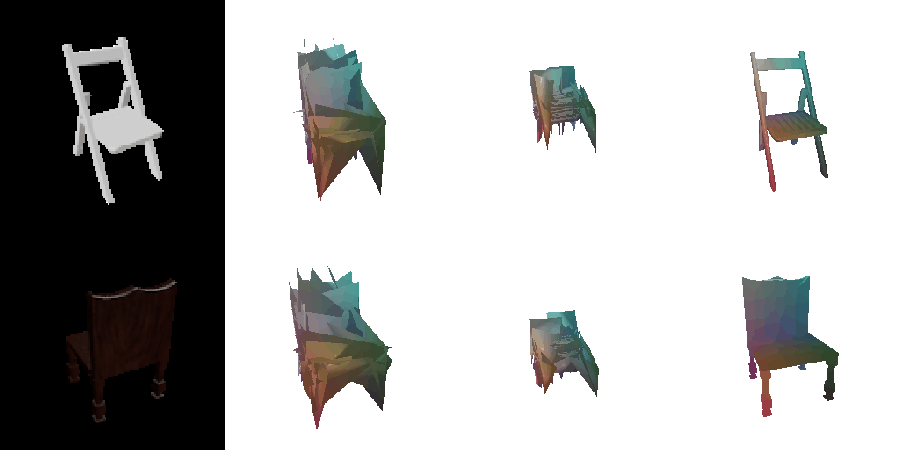
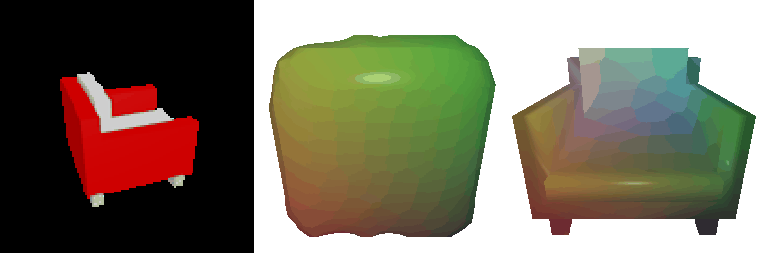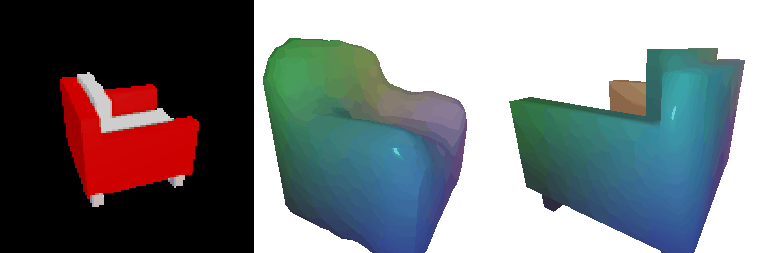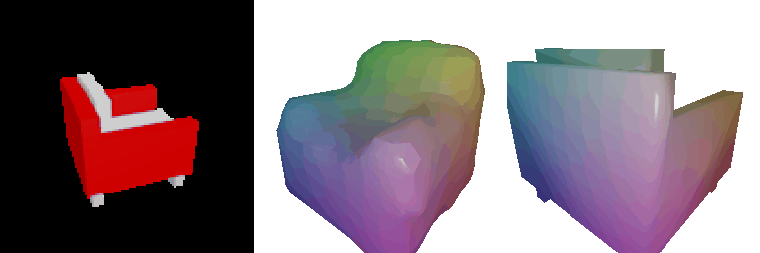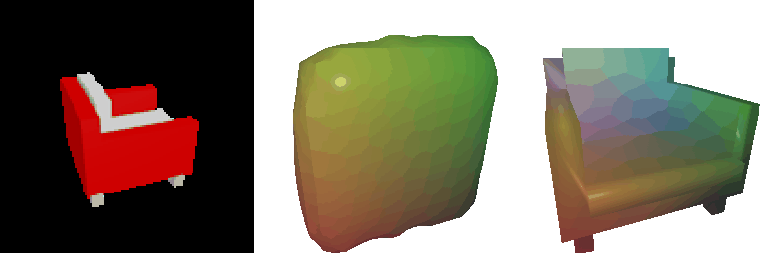
Left-to-right: input, ico_sphere(4) (radius 1.0), scaled-init mesh, ground truth.
All 3D panels rotate 360°, in a shared coordinate frame derived from the ground truth.
Baseline deforms a ico_sphere(4) with radius = 1 and free offsets, and the variant starts from the sphere scaled to 0.4 with offsets
capped at ±0.5. The scaled init gives tighter, less folded shapes, but F1 score drops. This shows that initialization scale fixes the folding, but the deformation range must still cover the shape distribution.
Interpolating the features (dimension = 512) of two images and decoding them into voxel representation gives a smooth, monotonic morph, showing that the decoder learned a continuous shape space.
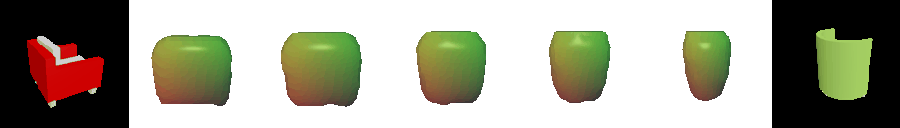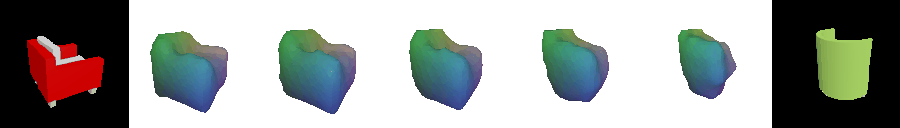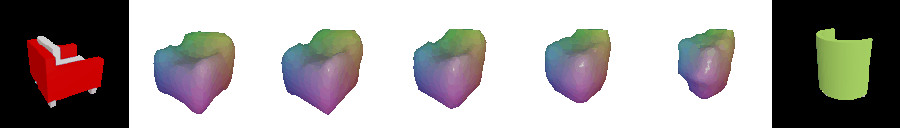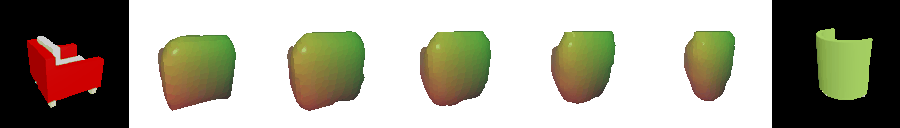 Left to right: input image A · interpolation weights
α = 0, 0.25, 0.5, 0.75, 1.0 · input image B
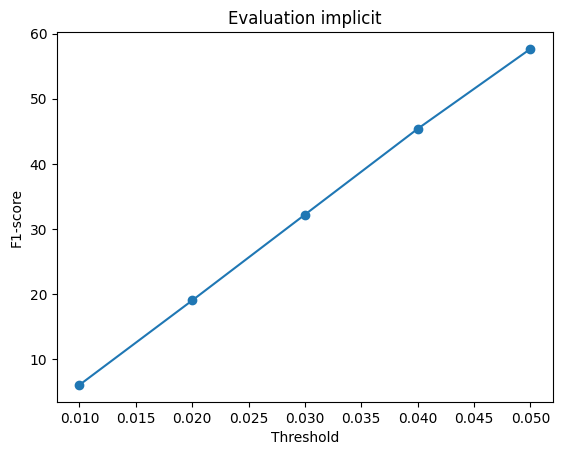
F1@0.05 = 57.66
Decoder: (image feature, 3D point) → occupancy
| F1@0.05 | |
|---|---|
| Voxel (transposed 3D conv, equal 10 000-iteration budget) | 58.38 |
| Implicit (coordinate MLP) | 57.66 |