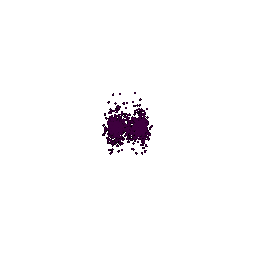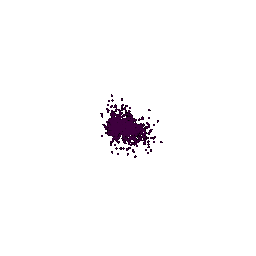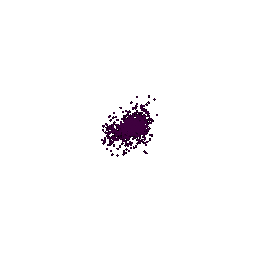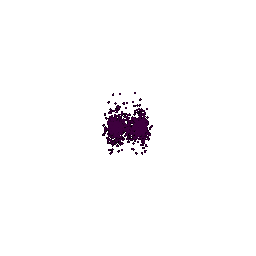
16-825 Assignment 2: Single View to 3D

1. Exploring Loss Functions (10 Points)

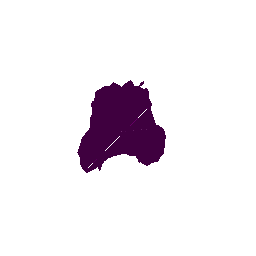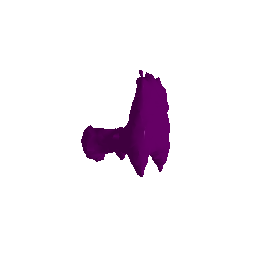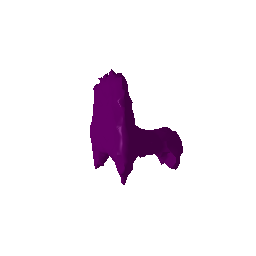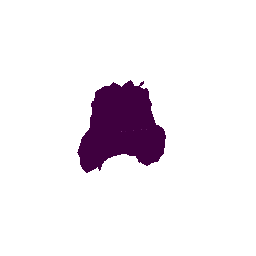
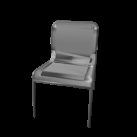
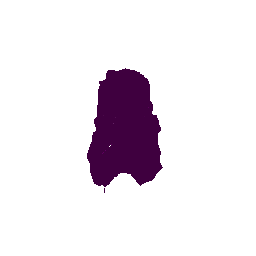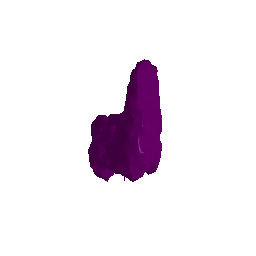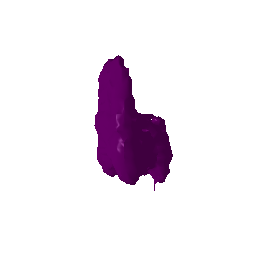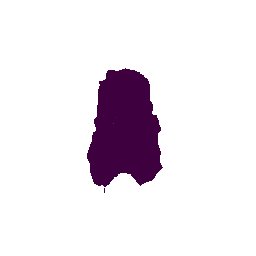
1.1 Fitting a Voxel Grid (4 points)

Optimized
Ground truth

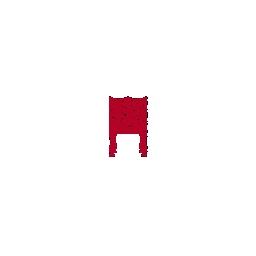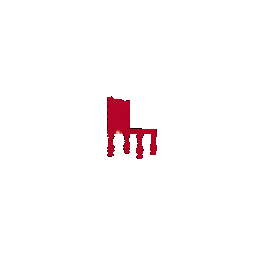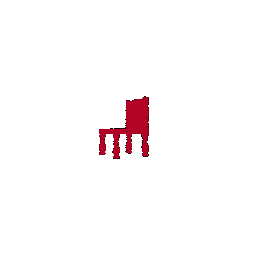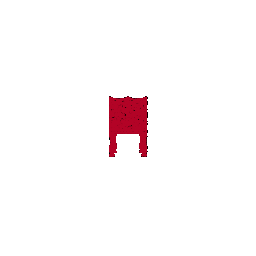
1.2 Fitting a Point Cloud (3 points)

Optimized
Ground truth

1.3 Fitting a Mesh (3 points)

Optimized
Ground truth

2. Reconstructing 3D from Single View (80 Points)

2.1 Image to Voxel Grid (20 points)

Example 1

Input RGB
Predicted voxels
Ground-truth mesh

Example 2

Input RGB
Predicted voxels
Ground-truth mesh

Example 3

Input RGB
Predicted voxels
Ground-truth mesh

F1@0.05$37.5$

2.2 Image to Point Cloud (20 points)

Example 1

Input RGB
Predicted point cloud
Ground-truth mesh

Example 2

Input RGB
Predicted point cloud
Ground-truth mesh

Example 3

Input RGB
Predicted point cloud
Ground-truth mesh

F1@0.05$66.65$

2.3 Image to Mesh (20 points)

Example 1

Input RGB
Predicted mesh
Ground-truth mesh

Example 2

Input RGB
Predicted mesh
Ground-truth mesh

Example 3

Input RGB
Predicted mesh
Ground-truth mesh

F1@0.05$65.35$

Mesh vs. point cloud vs. voxel grid
Voxel gridPoint cloudMesh
F1@0.05$37.5$$66.65$$65.35$
Training iterations$400$$100$$1000$
The point cloud and mesh decoders perform about the same ($66.65$ vs. $65.35$) and both are far ahead of the voxel decoder ($37.5$). The point cloud does best even though it trained for the fewest iterations. I believe this is due to the fact that the chamfer loss training objective is a similar operation to the F1 score (nearest neighbor distances), so it makes sense that the point cloud model performs the best as its objective is the same as this metric. The mesh model is also trained with chamfer, but it can only deform a fixed icosphere. A chair has holes, so the mesh has to stretch faces across them. Points sampled from those faces land where there is no ground-truth surface, which lowers precision.

2.4 Effects of Hyperparameter Variations (10 points)

I varied $n\in\{500, 1000, 5000\}$ (where $n$ is the number of points for the pointcloud model). I used the pretrained ResNet18 features, $100$ iterations, batch size $32$, learning rate $4\times10^{-4}$.

n_points$500$$1000$$5000$
F1@0.05$58.11$$66.65$$76.78$

Test example 1

500 points
1000 points
5000 points
Ground-truth mesh

F1 curves

500 points
1000 points
5000 points

AnalysisF1@0.05 rises steadily with the number of predicted points ($58.11 \to 66.65 \to 76.78$), because a denser prediction covers more of the chair's surface, especially thin legs and slats.

2.5 Interpret Your Model (10 points)

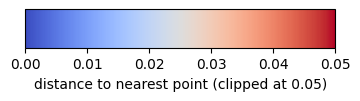
I colored the reconstructions by the nearest-neighbor distances (as in, nearest neighhbor to the ground truth mesh). Then each ground-truth point is colored by its distance to the nearest predicted point, so red points are parts of the chair the model missed.
Voxel grid, test sample 400

Input RGB
Precision error (prediction)
Recall error (ground truth)

Voxel grid, test sample 500

Input RGB
Precision error (prediction)
Recall error (ground truth)

Point cloud, test sample 200

Input RGB
Precision error (prediction)
Recall error (ground truth)

Mesh, test sample 200

Input RGB
Precision error (prediction)
Recall error (ground truth)

3. Exploring Other Architectures / Datasets

3.2 Parametric Network (10 points)

ApproachFollowing Deep Geometric Prior for Surface Reconstruction, the ground-truth point cloud is covered with overlapping local patches (Poisson-disk anchors, then ball queries until every point is covered). Each patch is normalized (centered, scaled, and rotated into its principal axes) and gets its own MLP $\phi_i: \mathbb{R}^2 \to \mathbb{R}^3$ mapping 2D samples to 3D points. Patches are first fit locally by matching $\phi_i(u, v)$ to the patch points with a Sinkhorn algorithm and MSE loss, then refined with a consistency pass that keeps those correspondences fixed. Finally the patches are upsampled to produce the reconstructed point cloud shown above.